Top FRP Platform Systems for Building Reactive Applications
2026-09-05
Reactive applications live or die by the platform underneath them. You need something that handles streams, state, and backpressure without falling apart — much like industrial flooring needs FRP grating that can take a beating. That's why we keep coming back to the same tough-minded approach, the kind you'd expect from Sino Grating. In this roundup, we'll walk through the top FRP platform systems that actually deliver when your app starts reacting to everything at once.
What Separates Durable FRP Platforms from Experiments
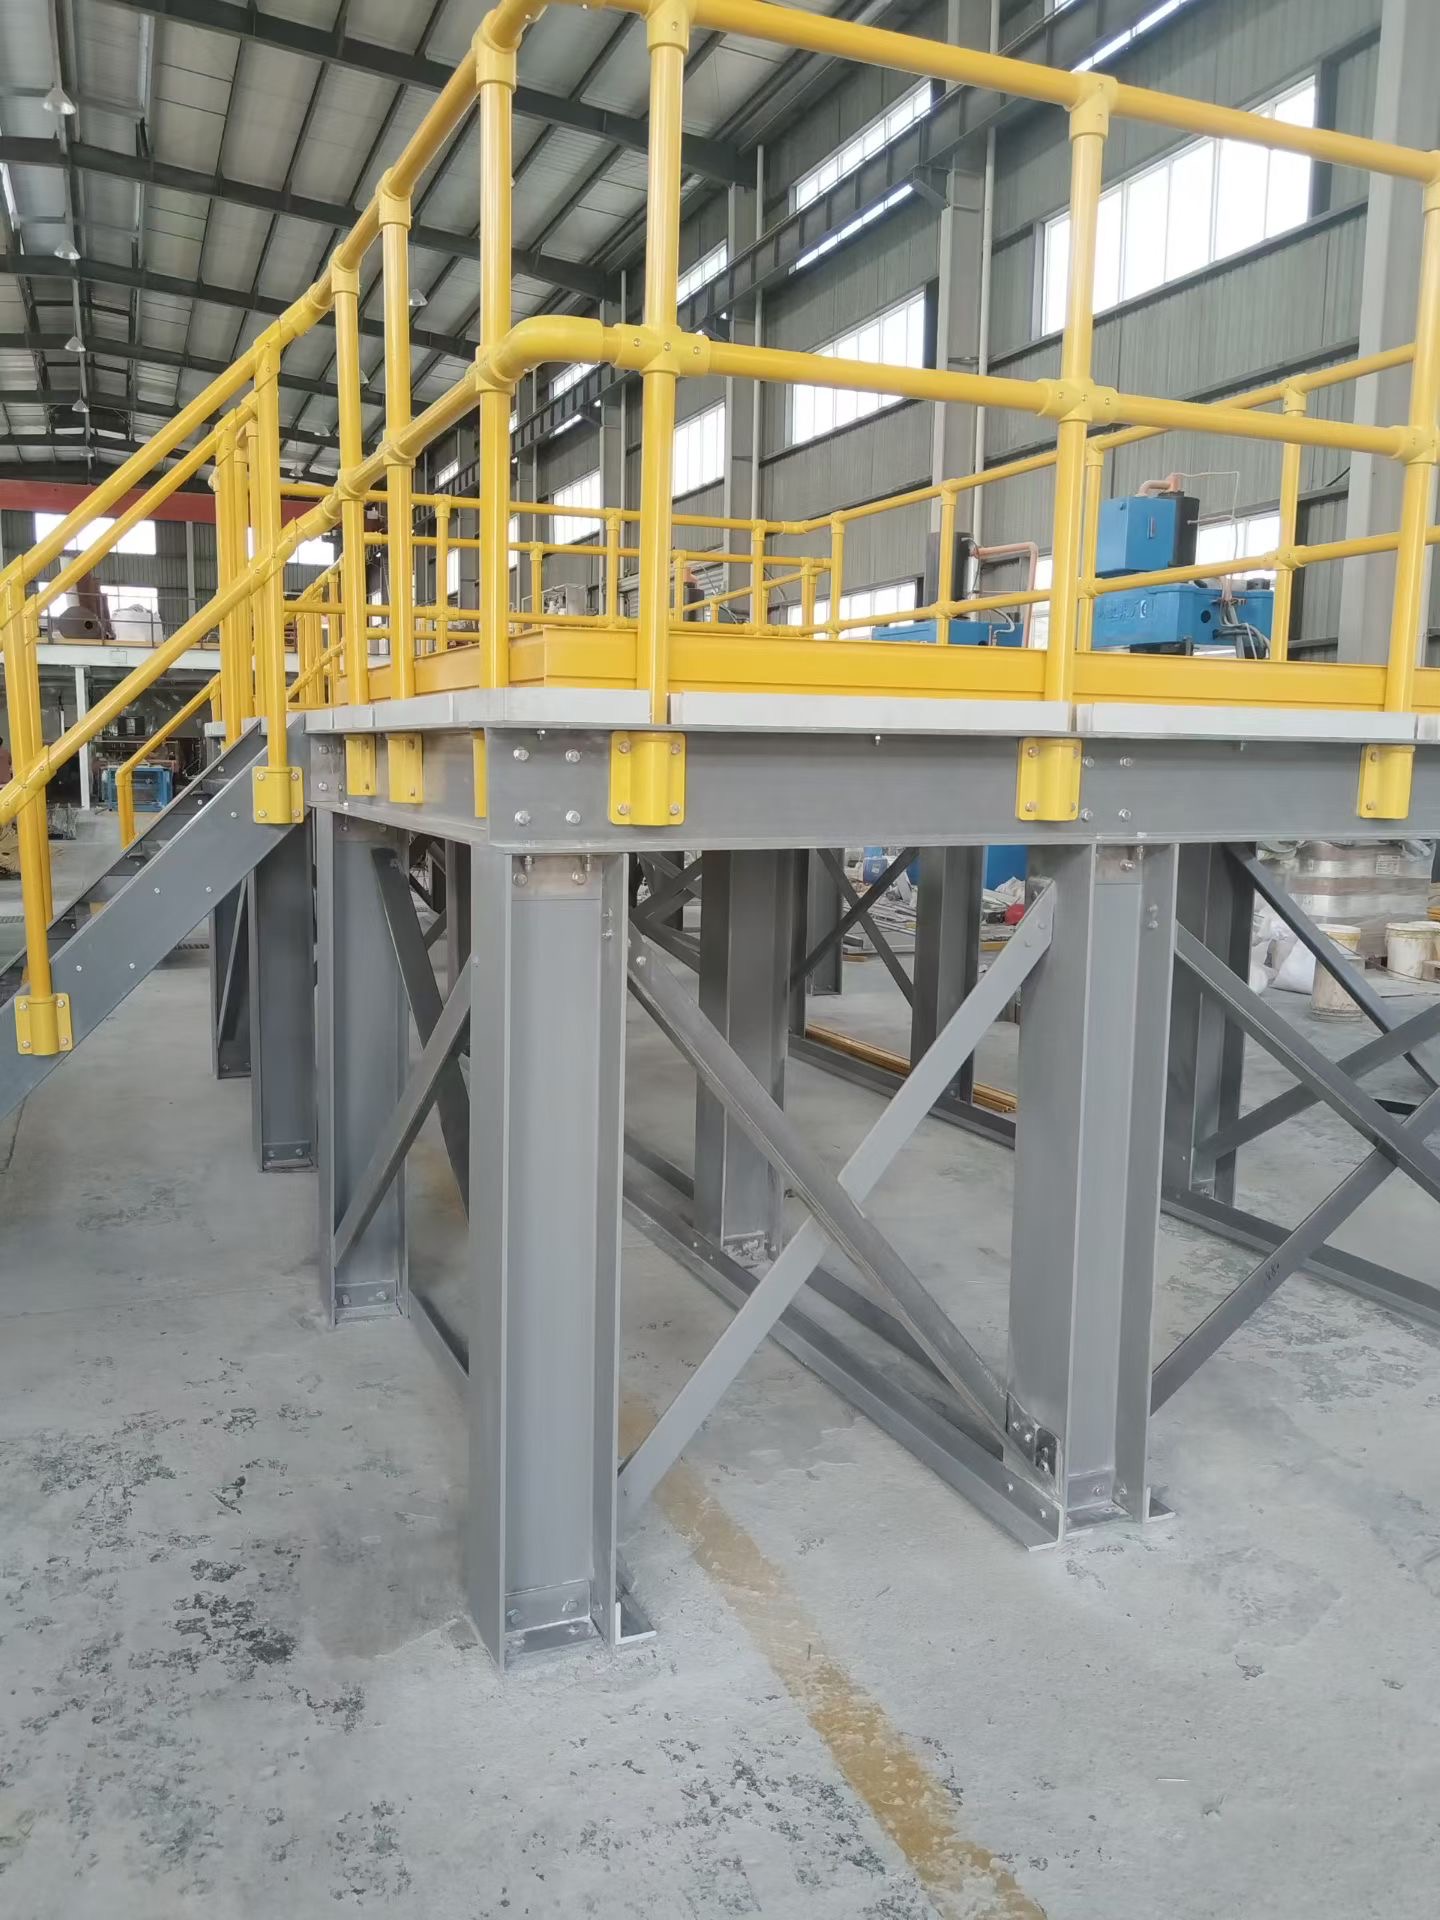
Most FRP platforms begin life as promising ideas, but only a fraction survive long enough to become dependable infrastructure. The difference often comes down to material selection and manufacturing discipline. Durable platforms use resins and glass fibers tested for fatigue, UV exposure, and chemical attack over years, not just weeks. They are built in controlled environments where fiber orientation and resin saturation are tightly managed, eliminating weak spots that lead to premature cracking or delamination.
Another separator is the way connections and load paths are handled. Experimental setups might rely on simplified joints or idealized support conditions, while durable platforms incorporate real-world details like corrosion-resistant fasteners, bonded joints with redundant seals, and reinforced cutouts for piping or access. These platforms are also designed with inspection and maintenance in mind, so a small surface wear mark doesn't become a hidden structural failure. Field data from installations in coastal, chemical, and high-traffic settings confirms that durable designs tolerate the same stresses that quickly degrade prototypes.
Finally, long-term performance is validated through independent testing and installed references. Durable FRP platforms carry documentation of accelerated aging tests, load cycling, and fire resistance ratings that match the actual service environment. They are not just a single successful trial but part of a product line with repeatable results across multiple projects. That track record, backed by engineering support and material traceability, is what moves a platform from experimental curiosity to a dependable asset for facility owners.
The Developer Experience Gap You Only Notice After Two Sprints
Two sprints in, the roadmap still looks tidy, but the daily reality has started to fray. Velocity metrics hover where they should, yet the pull requests tell a different story: small fixes bundled into unrelated features, half-written tests waiting for a “later” that never comes, and standups where people describe what they did instead of what they’re stuck on. The gap isn’t in the code—it’s in the friction between tools, missing context, and decisions that made sense in sprint planning but collapse under real dependencies.
What surfaces around day ten is rarely a single blocker. It’s the accumulated cost of switching between four dashboards to understand one failure. It’s the onboarding doc that hasn’t been updated since the last intern left, forcing every new hire to rediscover the same undocumented steps. It’s the local environment that works on one laptop and breaks on another, eating an afternoon for no visible output. None of these appear on a burndown chart, so they stay invisible until someone asks why a “simple” ticket took three days.
The teams that close this gap don’t start with a tool purchase or a process overhaul. They start by treating developer friction as first-class product debt—something to be triaged, owned, and fixed in small, boring increments. A ten-minute script that removes a manual step. A weekly “friction log” that gets reviewed like a bug queue. The goal isn’t a perfect workflow; it’s making the next sprint feel slightly less like wading through mud than the last one.
How Leading FRP Systems Tame Backpressure Without Breaking a Sweat
The best FRP implementations treat backpressure as a first-class citizen rather than a bolt-on fix. They propagate demand from subscribers all the way to the source, so a slow consumer naturally slows the producer instead of letting events pile up in memory. This pull-based rhythm keeps the whole pipeline aligned with actual processing capacity.
Many leading systems achieve this through dynamic batching or credit-based flow control. A downstream component grants a fixed number of credits, and the upstream side only sends data when credits are available. Buffers, when used at all, stay small and often carry a time-to-live, which keeps latency predictable even under sudden load spikes.
The result is a stream that absorbs bursts without manual tuning. Operators don't need to adjust queue sizes or thread pools whenever traffic patterns shift—the FRP layer adapts on its own. That's what makes backpressure feel almost invisible: the system simply does the right thing under pressure.
State Management Patterns That Actually Scale in Reactive Code
Most reactive codebases don't collapse because of missing features; they fray at the edges when state updates start crossing boundaries. A pattern that actually holds up treats state as a stream of immutable snapshots rather than scattered mutable variables. Instead of letting components subscribe to a dozen different observables and hope for consistency, you funnel everything through a single source of truth that emits versioned states. This doesn't mean everything lives in one giant object—scoping matters—but each domain slice should own its transition logic and expose a read-only view. Once you stop mutating state in place, rollback, time-travel debugging, and even replaying complex user flows become natural side effects of the architecture, not bolt-on tools.
The second piece is making state transitions explicit, ideally as plain data events that get reduced into the current state. Rather than calling setLoading from five different places and then wondering why spinners stick, you dispatch an intent like loadRequested and let a reducer decide what that means for the state. In reactive systems, those intents can themselves be streams, which lets you buffer, throttle, or debounce them without touching UI code. For larger apps, splitting the store by feature boundaries and composing reducers tends to scale better than one monolithic switch statement—each slice stays testable in isolation, and you avoid the merge-conflict hell that comes from everyone editing the same file. Add a thin layer of selectors or derived state, and you can keep components dumb, so the business logic stays in one place where it can be reasoned about version by version.
Real-World Migration Stories from Callback Hell to Predictable Streams
One backend team I joined had a payment processing pipeline that started as a simple series of three callbacks. Six months later, it was a twelve-level indentation monster where a single misplaced return silently dropped transactions. Debugging meant inserting console.log after every third line. Moving to streams forced us to break each step into named transform functions and chain them explicitly, which made the data flow visible at a glance.
The biggest surprise wasn't performance—it was how much easier it became to handle partial failures. Instead of try/catch blocks in each callback, we could catch once at the end of the stream and see the exact data that caused the error. One developer cut a 400-line file down to 80 lines without losing any logic, and the remaining code read like a set of cooking instructions rather than a maze of nested indentation.
Red Flags to Spot Before You Bet Your Architecture on a FRP Tool
A quick way to gauge whether a FRP tool deserves a place in your stack is to look at how its maintainers handle edge cases. If the repository is full of enthusiastic demo videos but the issue tracker shows months-old bug reports with no replies, that gap usually widens once you hit production traffic. The same goes for documentation that only covers happy paths—when the examples never mention backpressure, error recovery, or teardown, you'll likely end up writing your own workarounds after the first incident.
Another warning sign shows up when a tool quietly dictates how you should model state, schedule side effects, or structure your components. If adopting it means rewriting large parts of your domain layer just to fit its notion of streams or signals, the long-term cost tends to exceed the initial productivity boost. Healthy libraries sit at the boundary and let you choose the core patterns; risky ones leak their abstractions into every file until a simple change ripples across the entire codebase.
Pay attention to what happens when something goes wrong. A FRP tool that turns a straightforward bug into a maze of operator chains or leaves you staring at a wall of anonymous stack frames will quietly drain your team's velocity. Before committing, build a small spike that includes failure modes—dropped events, overlapping subscriptions, slow consumers—and see whether the tool helps you diagnose the problem or buries it under another layer of indirection.
FAQ
RxJava's popularity comes from its vast operator set and mature threading model, which let developers compose asynchronous workflows in a declarative style. The learning curve is real—concepts like backpressure and schedulers take time—but once internalized, they offer fine-grained control over concurrency that many backend teams find indispensable. It also benefits from a large community and plenty of production-tested libraries.
Elm uses a controlled architecture where side effects are described as data (commands and subscriptions) rather than performed directly. The runtime interprets these descriptions, so your application logic stays pure and predictable. This approach eliminates whole classes of runtime errors and makes refactoring much safer than in languages where effects can hide anywhere.
For a small team, I'd lean toward Bacon.js or RxJS if they already know JavaScript. Bacon's API is smaller and friendlier for beginners, while RxJS has more operators and better integration with Angular. If the team is open to a compile-to-JS language, Elm is excellent for dashboards because the compiler catches many UI state bugs before runtime, which speeds up development after the initial learning investment.
Discrete FRP deals with events that occur at specific times, like clicks or messages. Continuous FRP models values that change over time, such as mouse position or time itself. Most mainstream platforms—RxJava, Reactor, Bacon.js, RxJS—are discrete. True continuous FRP is rarer; libraries like Yampa and Dunai support it, but they are mostly used in specialized domains like animation, robotics, or games.
Flutter's stream-based approach feels lighter than full FRP because you're not forced to model every piece of state as a signal. Developers can use StreamBuilder where reactivity is needed and plain setState elsewhere. This reduces boilerplate and conceptual overhead, which is why many mobile teams adopt it even though it's technically not pure FRP. It offers pragmatic reactivity without the mind-shift that a platform like Sodium demands.
The most common pitfalls are overusing stateful operators like scan or replay, which create hidden memory leaks if not disposed properly, and mishandling backpressure across service boundaries. Teams also struggle with debugging because stack traces become less intuitive when everything is a stream. A good rule of thumb is to keep streams short and avoid mixing too many concerns in a single chain; otherwise, maintenance gets painful quickly.
FRP platforms focus on composing data flows over time using declarative operators, while actor frameworks emphasize isolated state and message passing between concurrent entities. Akka excels at fault tolerance and distribution, whereas RxJava or Reactor shine at transforming and combining asynchronous data streams within a single service. Many real-world systems use both: actors for supervision and FRP for pipelines inside actors or at the edges.
Conclusion
Building a reactive application on a FRP platform quickly separates tools that can survive real production loads from those that only shine in demos. The difference often appears after roughly two sprints, when developers face subtle friction in composing streams, debugging race conditions, or reconciling state across async boundaries. Durable platforms tend to treat backpressure as a first-class concern, not an afterthought. Their operators give you fine-grained control over buffering, dropping, or throttling events, which prevents memory blowups without requiring teams to hand-roll custom queues. This built-in resilience is what allows a small team to keep latency predictable even as event volume spikes.
State management in mature FRP systems follows a few repeatable patterns that scale past a single screen or service. Rather than scattering subjects and mutable variables, developers lean on unidirectional data flows, concentrated stores, and explicit derivation of view state from raw events. Real-world migration stories show teams escaping callback hell by gradually wrapping legacy imperative code behind stream adapters, then deleting the old paths once parity is reached. Before committing to any FRP tool, look for red flags such as weak documentation on error handling, poor debugging support for stream graphs, or a core maintainer community that has gone quiet. Those signs matter more than a feature checklist when the architecture is on the line.
Contact Us
Contact Person: Nicholas Zhu
Email: [email protected]
Tel/WhatsApp: 18921275456
Website: https://www.sino-grate.com